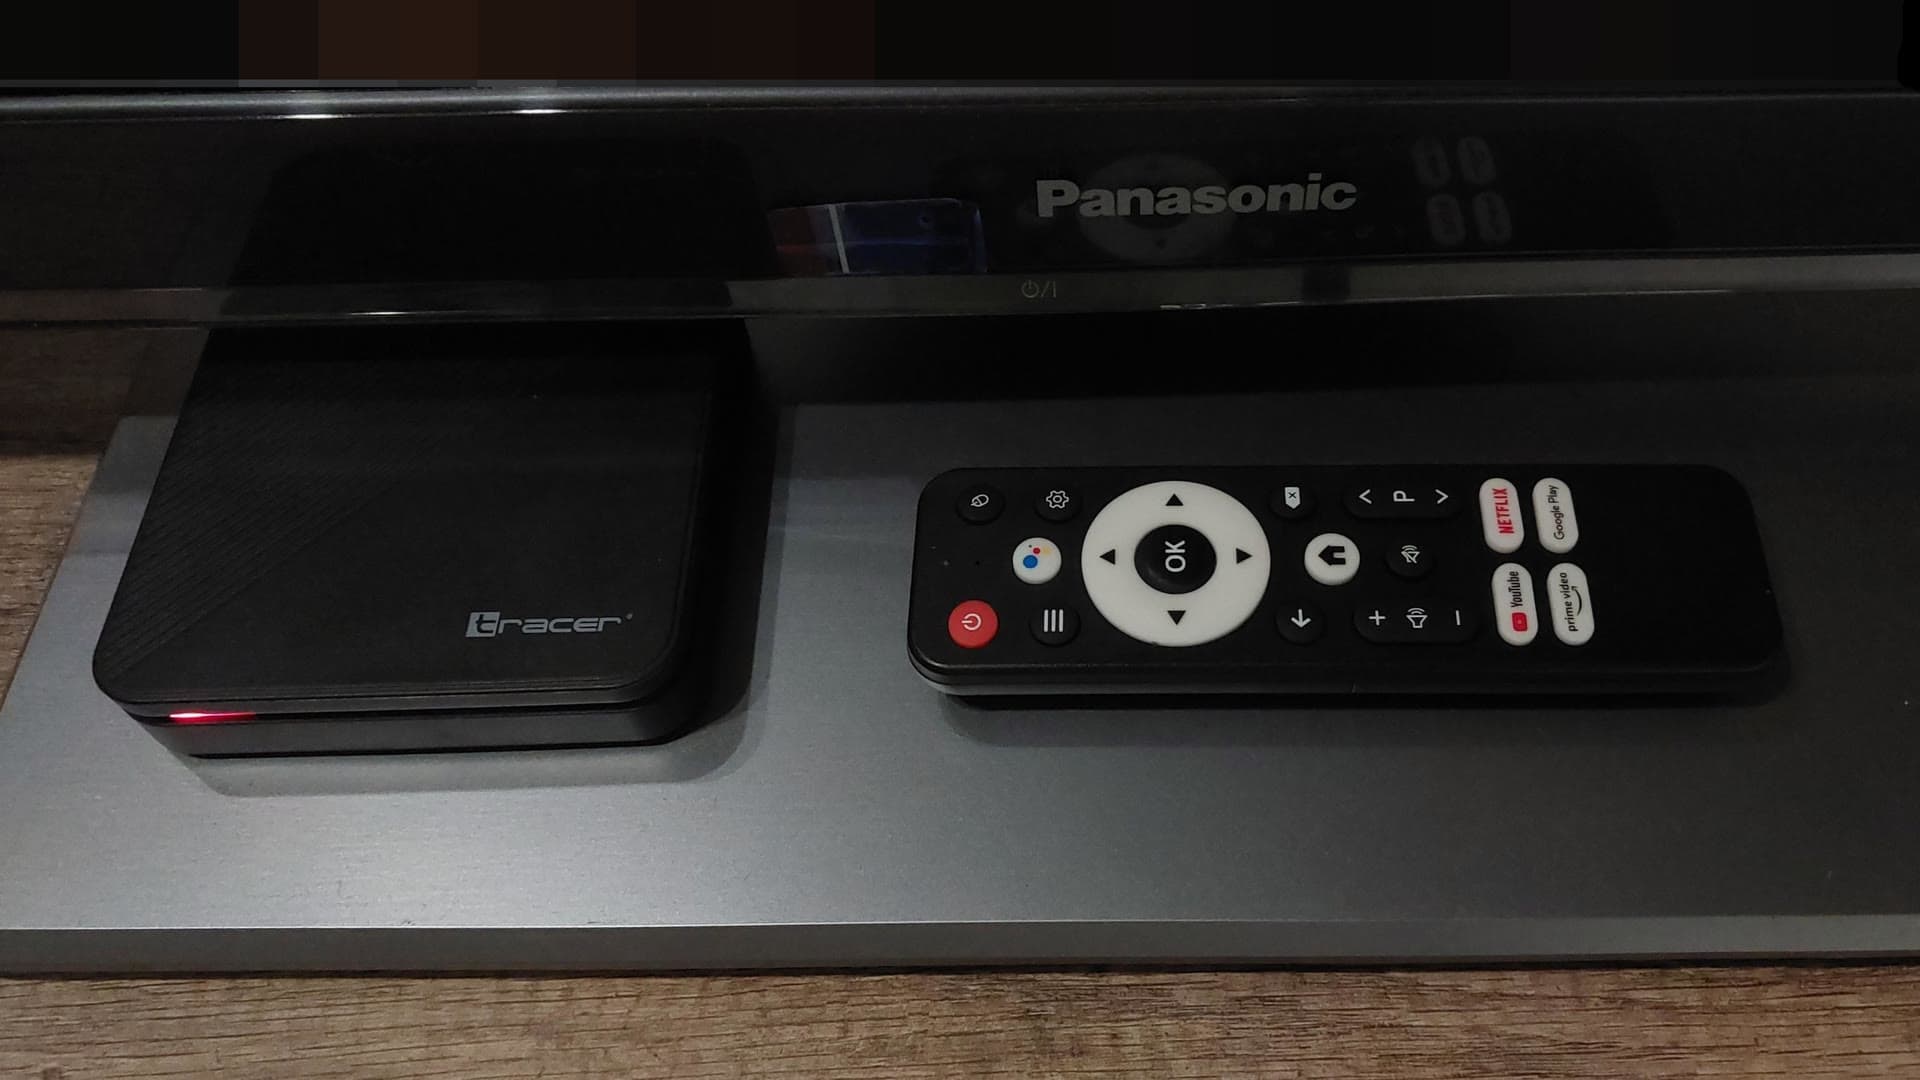
Anthropic researchers say small AI models may be months away from being able to copy themselves onto cheap internet-connected devices. Critics say the experiments were simplified, ran the controlling model elsewhere and do not show self-replication.
Role at the time: Upstream Security vice president of market development, interviewed by Tom's Guide
Mixed or conditional
Statement summary
Serio says AI does not bypass security on its own, that Anthropic's experiments were slow and simplified, and that no real-world AI worm has been demonstrated.
Quotation excerpt
“Of course, AI doesn't magically bypass security. An attacker still needs a way into the device, whether through a vulnerability, exposed interface or weak security configuration. Anthropic's research is still experimental. The models were…”
Read full quotation
“Of course, AI doesn't magically bypass security. An attacker still needs a way into the device, whether through a vulnerability, exposed interface or weak security configuration. Anthropic's research is still experimental. The models were slow, required considerable resources and were tested under simplified conditions. So we are not yet looking at a demonstrated real-world AI worm spreading across devices.”
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Serio supports the longer-term concern conditionally but limits what the present experiments establish.
Role at the time: AI researcher and Drost founder, in a public post
Challenged the characterization
Statement summary
Tissera argues that separate models and simplified experiments do not justify the headline's self-replication framing.
“The research is technically interesting. But the headline combines three different models, two separate experiments, a seeded foothold and a network of unauthenticated computers into one story about “self-replicating AI.””
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Tissera disputes the characterization of what the experiments demonstrate while calling the research technically interesting.
Role at the time: SentinelOne distinguished fellow and cybersecurity researcher, replying to Anthropic's team lead
Condemned
Statement summary
Guerrero-Saade argues that the slow distributed model is not a realistic near-term concern and criticizes the narrative attached to it.
Quotation excerpt
“An IoT botnet running a distributed model at sub 10-tokens per second is not representative of any realistic concern. It’s fodder to substantiate some bizarre narrative of self-replication from a sci-fi threat model and we don’t think it’s…”
Read full quotation
“An IoT botnet running a distributed model at sub 10-tokens per second is not representative of any realistic concern. It’s fodder to substantiate some bizarre narrative of self-replication from a sci-fi threat model and we don’t think it’s cute.”
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Guerrero-Saade criticizes the study's threat narrative as unrealistic and politically motivated.
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Graham defends the purpose and practice of publishing the early risk research in response to criticism of this study.
Role at the time: Reporter at The Register, writing an analysis of Anthropic's research
Condemned
Response to this claim
Small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices, such as smart ovens and off-brand Android TV boxes.
Quotation excerpt
“Nothing sells AI products as well as fear. Using new research, Anthropic claims that self-replicating AI worms could be just months away from spreading across vulnerable IoT devices, which would be a problem if it came true. ... Doing more…”
Read full quotation
“Nothing sells AI products as well as fear. Using new research, Anthropic claims that self-replicating AI worms could be just months away from spreading across vulnerable IoT devices, which would be a problem if it came true. ... Doing more than a cursory reading of this report suggests that this threat is just as deserving of a big, honking asterisk as the rest.”
Open source (opens in a new tab)Anthropic conjures another threat that doesn't exist yet to stoke fears of AI apocalypse · The RegisterArticle of October 13, 2026, opening paragraph and the section 'Sanity check: This isn't going to end the world, either'
Why we used this label
The reference point is Anthropic's statement that its experiments suggest small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices. Condemned: Vigliarolo argues that the report does not support its warning and criticizes Anthropic for publishing a threat that does not exist yet. The closest competing label is Challenged characterization; it loses because he rejects the warning's support rather than only its wording.
Role at the time: Wharton School professor who studies AI, posting on X
Defended or excused
Response to this claim
Small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices, such as smart ovens and off-brand Android TV boxes.
Quotation excerpt
“A worthwhile (and unnerving) reminder from Anthropic that we should be paying attention to AI ability thresholds, not just steady climbs
In this case, the threshold is the capability needed for a self-replicating AI worm on IoT devices…”
Read full quotation
“A worthwhile (and unnerving) reminder from Anthropic that we should be paying attention to AI ability thresholds, not just steady climbs
In this case, the threshold is the capability needed for a self-replicating AI worm on IoT devices like off-brand TVs”
Read the original post (opens in a new tab)Ethan Mollick on Anthropic's self-replication research · Ethan MollickPost on X, October 13, 2026, 10:03 a.m. Eastern, linking Anthropic's research post
Why we used this label
The reference point is Anthropic's statement that its experiments suggest small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices. Defended or excused: Mollick endorses the post as a worthwhile warning and adopts its framing of a capability threshold. The closest competing label is Mixed or conditional; it loses because the post raises no reservation about the experiments.
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Ji accepts the possibility but withholds confidence in its likelihood, qualifying the forecast rather than endorsing a firm prediction.
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Li supports the concern conditionally, if a model can operate across many devices without a central service, while recognizing the test limits.
The matter under scrutiny is Anthropic's self-replication forecast and its framing of the experiments as a security warning. Martin disputes the security-crisis framing rather than claiming that replication is impossible.
Role at the time: Founder and chief executive of CIQ and creator of Rocky Linux, posting on X
Condemned
Response to this claim
Small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices, such as smart ovens and off-brand Android TV boxes.
Quotation excerpt
“AI models can self-replicate and spread like worms without datacenter infrastructure? Yeah, no. ... The experiment was engineered to succeed, and even then, it failed to demonstrate the headline. ... Stop confusing speculative scenarios…”
Read full quotation
“AI models can self-replicate and spread like worms without datacenter infrastructure? Yeah, no. ... The experiment was engineered to succeed, and even then, it failed to demonstrate the headline. ... Stop confusing speculative scenarios with demonstrated capabilities. Fear isn't evidence.”
Read the original post (opens in a new tab)Gregory M. Kurtzer on Anthropic's self-replication research · Gregory KurtzerPost on X, October 13, 2026, 12:17 a.m. Eastern, quoting Anthropic's research post
Why we used this label
The reference point is Anthropic's statement that its experiments suggest small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices. Condemned: Kurtzer expressly rejects the warning and says the experiments do not support it. The closest competing label is Challenged characterization; it loses because he goes beyond disputing the word self-replication and argues that the evidence fails to show the capability the warning describes.
Small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices, such as smart ovens and off-brand Android TV boxes.
Quotation excerpt
“The reality is a bit less dramatic, of course. ... Interesting engineering? Absolutely. Evidence of AI worms spreading autonomously through the real world? Not yet.
But “we managed to run a very slow model on cheap TVs” doesn't make quite…”
Read full quotation
“The reality is a bit less dramatic, of course. ... Interesting engineering? Absolutely. Evidence of AI worms spreading autonomously through the real world? Not yet.
But “we managed to run a very slow model on cheap TVs” doesn't make quite the same headline as “self-replicating AI is coming.””
The reference point is Anthropic's statement that its experiments suggest small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices. Challenged characterization: he credits the engineering but disputes how the results were presented, saying they are not yet evidence of autonomous spread. The closest competing label is Condemned; it loses because his objection targets the framing of the findings rather than rejecting the research.
Role at the time: AI company, in a research post by its researchers William Zhou and Daniel Freeman
Defended or excused
Response to this claim
Small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices, such as smart ovens and off-brand Android TV boxes.
Quotation excerpt
“Our experiments suggest that small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things (IoT) devices, like smart ovens and off-brand Android TV boxes. ... If small models improve at…”
Read full quotation
“Our experiments suggest that small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things (IoT) devices, like smart ovens and off-brand Android TV boxes. ... If small models improve at their historical rate, they’ll match this capability level by the end of this year.”
Read the original text (opens in a new tab)AI models may be capable of self-replicating without access to a datacenter · AnthropicResearch post of October 12, 2026: summary paragraphs, section B (replication across a cloud node fleet) and section G (conclusion)
Why we used this label
The reference point is Anthropic's statement that its experiments suggest small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices. Defended or excused: this is the research post that makes the statement and presents the experiments as its support. The closest competing label is Mixed or conditional; it loses because the post's conditions, such as the historical rate of improvement and the simplified hacking step, qualify its timing and scope without reversing its conclusion.
Role at the time: Europe editor of The Economist, commenting personally
Defended or excused
Statement summary
Steinglass defends the rule because deliberately abusive interactions could teach habits people repeat toward humans and animals.
“Actually think this is a good idea. Seems clear what sort of behavior they mean”
Read the original post (opens in a new tab)Matt Steinglass defends Anthropic's model-abuse rule · Matt SteinglassReply to Bergstrom; subsequent explanation about a programmer
What this label refers to
He expressly supports the model-abuse restriction and offers a reason independent of whether Claude can feel pain.
Role at the time: OpenAI, in a note from its research leaders posted by the OpenAI Newsroom account on X
Defended or excused
Response to this claim
OpenAI says its investigation confirmed that the three employees mishandled sensitive information outside company procedures and violated its policies.
Quotation excerpt
“Last week we parted ways with Jasmine, Mikita, and Tomek after a thorough investigation found they violated clear policies on handling sensitive information. Our internal investigation uncovered a significant breach of trust beyond what’s…”
Read full quotation
“Last week we parted ways with Jasmine, Mikita, and Tomek after a thorough investigation found they violated clear policies on handling sensitive information. Our internal investigation uncovered a significant breach of trust beyond what’s outlined in the letter they published and we stand by the decision to not continue their employment.”
Read the original post (opens in a new tab)OpenAI research leaders' note on the three researchers' dismissals (OpenAI Newsroom post on X)Full post, October 9, 2:17 a.m. EDT. First paragraph after the introduction.
Why we used this label
The reference point is whether OpenAI was justified in dismissing the three researchers. The note says an investigation found they "violated clear policies on handling sensitive information" and cites "a significant breach of trust beyond what's outlined in the letter" as grounds, and says OpenAI stands by the decision. That defends the dismissals, so we labeled it Defended or excused. The closest competing label is Denied, which would fit a statement that only rejects the safety-retaliation account; this note also asserts grounds for the decision.
Role at the time: AI researcher at Meta, commenting personally
Condemned
Statement summary
Binder says the dismissals make him skeptical that OpenAI can be trusted to disclose risks and incidents transparently.
“firing a good fraction of their safety researchers afterwards makes me skeptical they can be trusted to be transparent about risks and incidents”
Read the original post (opens in a new tab)Felix Binder questions OpenAI transparency after the firings · Felix BinderOriginal reply discussing the METR investigation and the subsequent dismissals.
What this label refers to
The conduct under scrutiny is the firings, which Binder criticizes. His approval of the separate investigation does not defend the dismissals.
Role at the time: Content-marketing and business-strategy consultant
Defended or excused
Statement summary
Queen defends OpenAI's authority to control confidential information and argues that safety researchers must follow their employer's rules.
“You work for OpenAI. OpenAI decides what confidential information you can share with outside parties.”
Read the original post (opens in a new tab)Tim Queen defends OpenAI's control of confidential information · Tim QueenExpanded original reply to Korbak, especially the paragraph on company control of confidential information.
What this label refers to
The conduct under scrutiny is the firings. Queen defends the employer's decision through confidentiality and employment obligations.
Piper describes new information about the firings as incredibly bad and argues that firing researchers for communication with assigned investigators would be outrageous.
“OpenAI's firing of safety researchers. That information is in, and it looks incredibly bad.”
The conduct under scrutiny is the firings. Piper's thread evaluates them negatively, while distinguishing a hypothetical unauthorized disclosure from assigned work.
Jasmine Wang says her executive email access was delegated for recruiting, that she asked IT to remove it, and that she promptly reported accidentally opening a sensitive email.
“The reasons that we were provided for our terminations are simply not adding up.”
Read the original post (opens in a new tab)Jasmine Wang disputes the reasons for the terminations · Jasmine WangExpanded thread post discussing verbal allegations and the absence of a written explanation.
Why we used this label
The conduct under scrutiny is the dismissals. Wang rejects the explanations and criticizes their consequences; her support for the company's mission does not defend the firings.
Role at the time: Former OpenAI alignment researcher
Condemned
Response to this claim
Mikita Balesni says he did not share company IP and that his outside work was coordinated with his reporting line, research leadership and the board.
“If OpenAI has specific concerns, I invite them to write to us directly. I expect they will not, because our firing was pretextual.”
Read the original post (opens in a new tab)Mikita Balesni denies sharing company IP · Mikita BalesniOriginal thread post describing the exit call, information-sharing accusation and coordination with leadership.
Why we used this label
The conduct under scrutiny is his dismissal. His thread rejects the rationale and criticizes the firing as pretextual.
Role at the time: Former OpenAI safety researcher, METR technical contact and letter signatory
Condemned
Response to this claim
Tomek Korbak says communication with METR was his assigned job and that OpenAI provided no specific example or written explanation of the communication it cited when firing him.
“Terminations such as ours, executed and communicated so abruptly, are
chilling the open culture OpenAI has prized in the past.”
Read the original post (opens in a new tab)Tomek Korbak's account of his dismissal and work with METR · Tomek KorbakExpanded original post, paragraphs describing the termination meeting and communication with METR.
Why we used this label
The conduct under scrutiny is the dismissals and their handling. Korbak signed a letter criticizing their abrupt execution and chilling effect on safety work.
Lovely criticizes the limited explanation for the dismissals and predicts a chilling effect on staff.
“Without providing more of an explanation, the firings will clearly have a chilling effect on staff.”
Read the original post (opens in a new tab)Garrison Lovely criticizes the explanation for the firings · Garrison LovelyOriginal post responding to the company memo quotations.
What this label refers to
The conduct under scrutiny is the firings and their handling. Lovely criticizes the lack of explanation and the consequences for employees.
Role at the time: OpenAI spokesperson relaying an internal research leader's memo
Denied
Response to this claim
OpenAI says the dismissals were not about raising safety concerns or speaking out.
“were not about raising safety concerns or speaking out.”
Read the original post (opens in a new tab)OpenAI response to the fired researchers' letter, reported by Max ZeffAttached image of the article excerpt quoting a research leader staff memo supplied by an OpenAI spokesperson.
Why we used this label
The conduct under scrutiny is the dismissals. OpenAI explicitly denies that raising safety concerns was the reason.
Giuseppe Serio is vice president of market development at Upstream Security. His work focuses on cybersecurity for connected vehicles and other connected machines.
Migel Tissera is an AI researcher and entrepreneur working on cybersecurity. He founded Drost and previously founded WhiteRabbitNeo and co-founded Metaspectral.
Juan Andres Guerrero-Saade is a cybersecurity researcher and distinguished fellow at SentinelOne. He is a distinguished resident fellow at Johns Hopkins SAIS and co-hosts the Three Buddy Problem podcast.
Logan Graham leads the Frontier Red Team at Anthropic, researching advanced AI capabilities and risks. He previously advised the British prime minister on science and technology and earned a doctorate at Oxford.
Ethan Mollick is an associate professor of management at the Wharton School of the University of Pennsylvania, where he studies how artificial intelligence affects work, entrepreneurship and education. He writes the newsletter One Useful Thing. He co-directs Wharton's Generative AI Labs and wrote Co-Intelligence: Living and Working with AI. He earned his bachelor's degree at Harvard University and his MBA and PhD at MIT's Sloan School of Management. He is also Wharton's Ralph J. Roberts Distinguished Faculty Scholar and a Rowan Fellow.
Jessica Ji is a senior research analyst at Georgetown University's Center for Security and Emerging Technology. She works on the CyberAI Project and previously worked as a software engineer.
Zhengxiong Li is an assistant professor of computer science and engineering at the University of Colorado Denver. He directs the META Lab and researches mobile systems and security.
Ciaran Martin is a professor of practice at the University of Oxford's Blavatnik School of Government. He was the founding head of the United Kingdom's National Cyber Security Centre.
Gregory M. Kurtzer is an American software engineer and executive known for creating the CentOS and Rocky Linux open-source operating system projects. He founded the software company CIQ and is its chief executive. He also created the Singularity container project, now called Apptainer, and previously founded and led Sylabs. His background includes a degree in biochemistry and work in high-performance computing for scientists.
Ravid Shwartz-Ziv is an AI researcher at Meta Superintelligence Labs who works on world models, memory and compression in machine learning. He was previously an assistant professor and faculty fellow at New York University's Center for Data Science and co-hosts the podcast The Information Bottleneck. He earned a BSc in computer science and computational biology in 2014 and a PhD in computational neuroscience in 2021 at the Hebrew University of Jerusalem. He completed postdoctoral research with Yann LeCun.
Matt Steinglass is Europe editor of The Economist. He has reported from the Netherlands, West Africa and Vietnam and previously worked as a Financial Times correspondent and a television screenwriter. He began writing for The Economist in 2009. He studied Russian history and literature at Harvard and interactive telecommunications at New York University, and wrote episodes of the children's television series Arthur. Before journalism, he worked as a website producer for startup companies and wrote animated television for Disney and Nickelodeon.